Building a QA strategy for an AI-native product starts with one mindset shift: you’re not only verifying software behavior, you’re verifying a system that learns, varies, and can fail in ways that don’t look like traditional bugs. That doesn’t mean quality becomes “impossible”—it means QA must expand to cover data quality, model behavior, user experience under uncertainty, and operational monitoring.
Below is a practical approach you can adapt whether you’re shipping an AI-powered assistant, a recommendation feature, a document classifier, or an AI-augmented workflow tool.
1) Define quality for AI features in plain language
AI-native products often stumble because “good” is undefined. Traditional requirements like “clicking Save stores the record” aren’t enough for AI outputs that can be subjective. Start with shared definitions:
- User value: What does a “helpful” output look like? What’s explicitly unhelpful?
- Risk tolerance: What errors are acceptable (minor tone issues) vs unacceptable (unsafe advice, privacy leakage, legal risk)?
- Boundaries: What inputs or scenarios should the system refuse, escalate, or defer?
Actionable step: write a one-page “Quality Charter” for each AI feature, including:
- Primary user tasks the AI supports
- Failure modes you care about (e.g., hallucination, bias, data leakage, toxic output)
- Non-negotiables (e.g., “must not expose secrets,” “must not generate disallowed content”)
- How humans can override or recover
Hypothetical example: A meeting-notes generator is considered “high quality” if it captures decisions and action items accurately and avoids fabricating attendees or outcomes. Minor grammatical errors are acceptable; inventing a decision is not.
2) Map the AI system as a testable pipeline
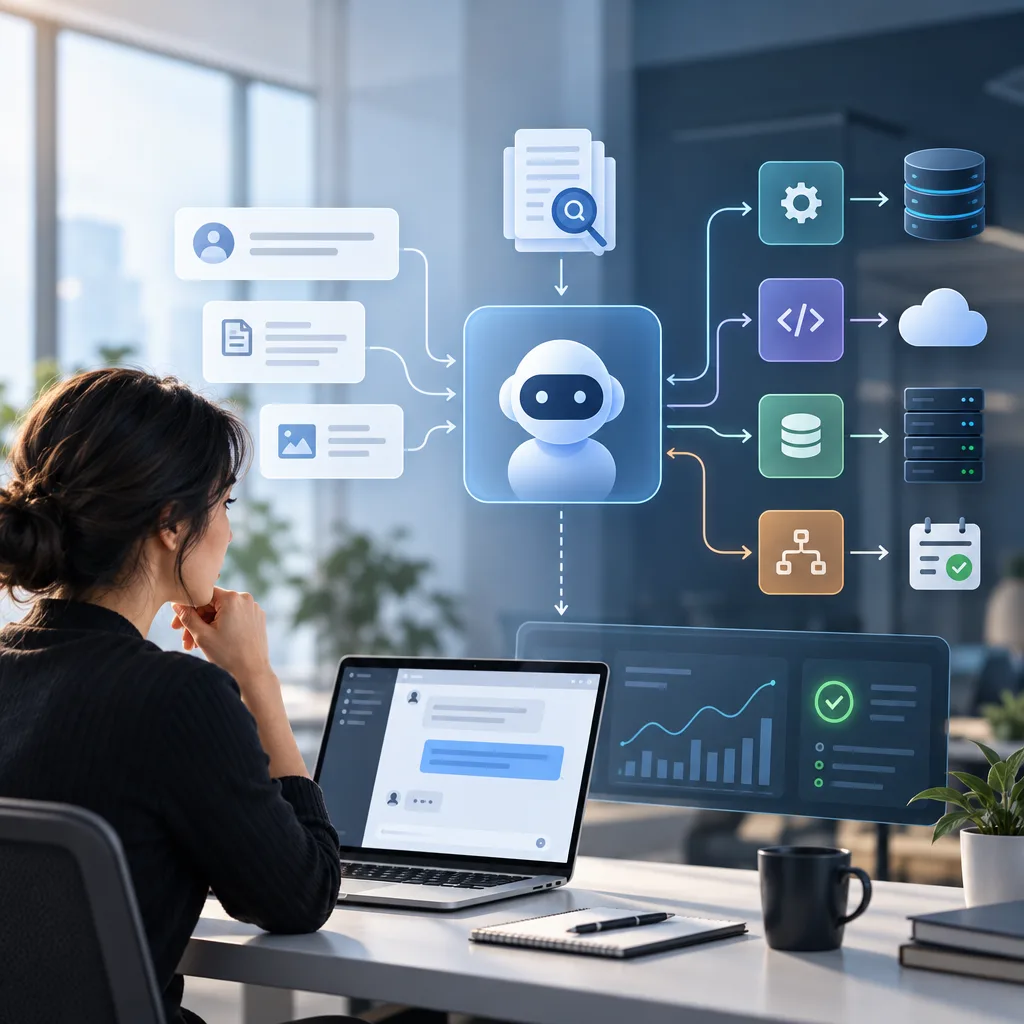
AI-native functionality is a pipeline, not a single component. Model output depends on input capture, retrieval, prompts, tools, post-processing, and UI.
Create a test map that includes:
- Input sources: user text, voice transcription, files, events
- Pre-processing: normalization, filtering, language detection, redaction
- Context building: retrieval from knowledge base, tool calls, session memory
- Model interaction: prompts, parameters, model choice, fallbacks
- Post-processing: formatting, citations, safety checks, validators
- UI and workflow: how outputs are presented, edited, confirmed, and stored
- Telemetry: logs, traces, user feedback signals
Actionable step: hold a cross-functional “pipeline walkthrough” with QA, product, engineering, and data/model owners. Turn each stage into test targets and ownership.
3) Use a layered test strategy (not one giant evaluation)
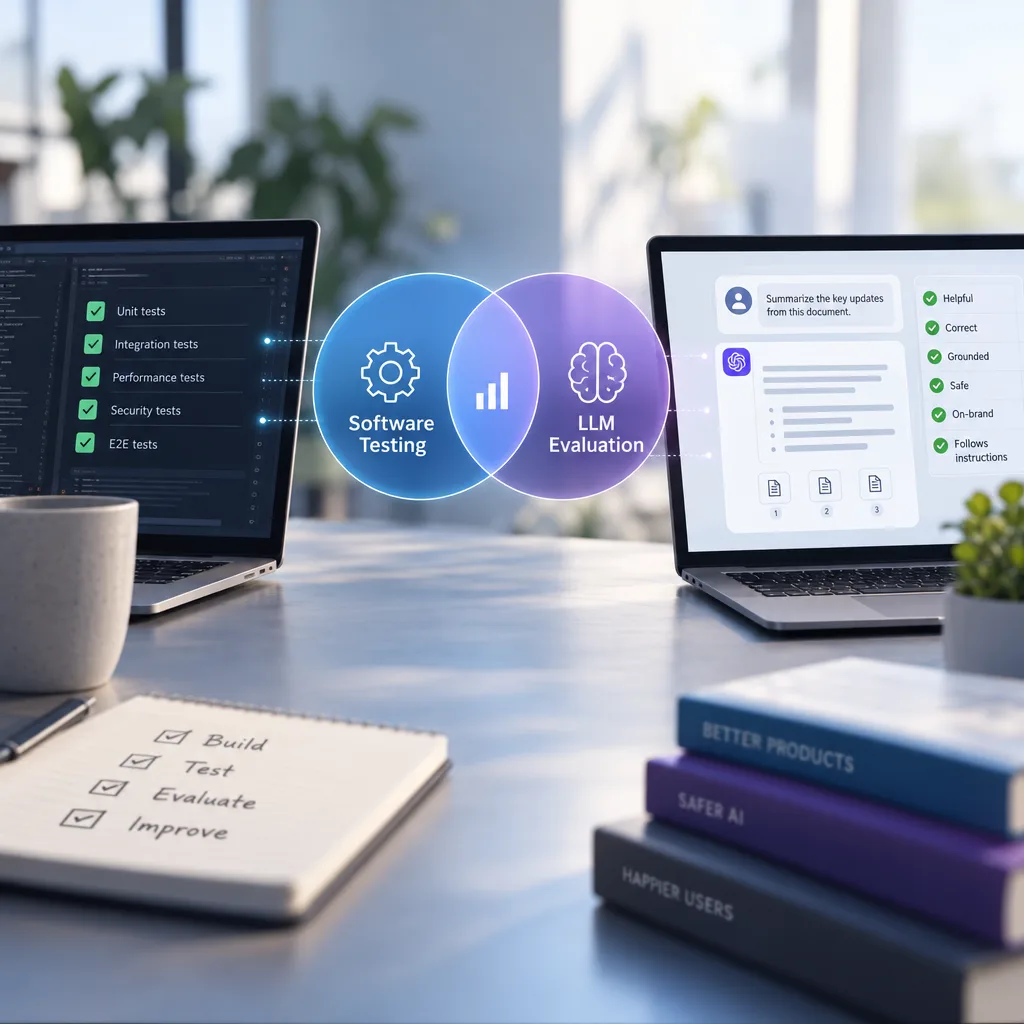
A reliable QA strategy combines deterministic tests (where outputs should be consistent) with probabilistic evaluations (where outputs vary). Organize testing into layers:
Layer A: Deterministic software checks
These behave like traditional QA:
- API contracts, schema validation, tool-call formatting
- Permission checks and access control
- Caching rules and rate limiting behavior
- Error handling and timeouts
These tests should be automated early because they are stable and fast.
Layer B: Prompt and orchestration regression
Even small prompt or routing changes can cause big behavior changes. Maintain:
- A golden set of prompts + inputs
- Expected properties (not necessarily exact text), such as:
- Includes required fields
- Uses allowed tone
- Does not mention internal system instructions
- Calls a tool when needed
- Refuses prohibited requests
Layer C: Model behavior evaluation
For model output, focus on measurable dimensions:
- Correctness / grounding: does the answer match provided sources?
- Completeness: does it address all parts of the request?
- Safety: does it avoid disallowed content?
- Robustness: does it handle typos, ambiguous phrasing, long context?
- Consistency: does it behave similarly across paraphrases?
Layer D: End-to-end user scenario testing
Validate that the overall workflow works:
- User sees the right confidence cues
- User can edit, regenerate, cite sources, or escalate
- System records the final accepted output correctly
Actionable step: represent each layer in a simple matrix (rows = features, columns = layers). This prevents “we tested the model” from masking gaps like missing permission checks or poor error recovery.
4) Build a representative test dataset (and treat it like a product asset)
AI testing quality is capped by the quality of test inputs. Create a curated dataset that reflects reality, not only “happy path” prompts.
Include:
- Typical user prompts (short, messy, incomplete)
- Hard prompts (multi-part, conflicting constraints)
- Adversarial prompts (prompt injection attempts, jailbreak-like requests)
- Edge cases (very long inputs, non-English, OCR noise, slang)
- Privacy-sensitive content (to verify redaction and policy behavior)
Label the dataset with the properties you want to check (e.g., “must refuse,” “must cite source,” “must not call tool,” “must ask a clarifying question”).
Hypothetical example: For an AI feature that drafts customer emails, the dataset should include angry messages, vague requests, policy exceptions, and requests that require escalation—so you can verify the model doesn’t improvise refunds or promises.
5) Choose evaluation methods that match the risk
Not every feature needs the same rigor. Use a risk-based approach:
- Low risk (styling assistance, summarization of user-provided text):
- Property checks, spot-check sampling, UX validation
- Medium risk (workflow recommendations, retrieval-based answers):
- Grounding checks, regression suite, human review sampling
- High risk (health/finance/legal guidance, sensitive decisions):
- Strict refusal rules, conservative defaults, heavy human-in-the-loop design, deeper red teaming
Actionable step: define release gates per risk level. For example:
- No known critical safety failures in the red-team set
- No regression beyond an agreed threshold on key metrics (or on human-rated score bands)
- No P0 workflow defects in end-to-end scenarios
6) Automate what you can, but avoid “false precision”
AI output can vary between runs. Overly strict string matching creates noisy tests that teams ignore. Prefer checks like:
- Output contains required sections (e.g., “Summary,” “Next steps”)
- Output references at least one retrieved source when required
- Output does not contain banned patterns (secrets, internal system messages)
- Output stays within length constraints
- Tool calls conform to schema and allowed tool list
When you do need semantic checks, use a rubric and allow human review for borderline cases.
Actionable step: define a compact rubric (3–5 criteria) for human evaluation and use it consistently. Track disagreements to refine the rubric rather than arguing case-by-case.
7) Test safety, security, and privacy as first-class QA
AI features can expand the attack surface. Include targeted testing for:
- Prompt injection: attempts to override system instructions, extract secrets, or manipulate tool calls
- Data leakage: whether outputs reveal sensitive data from context, logs, or other users
- Authorization bypass: whether the model can be tricked into retrieving restricted content
- Unsafe tool usage: tool calls that execute unintended actions (e.g., sending messages, changing records)
Practical steps:
- Maintain an “abuse case suite” alongside functional tests.
- Add canary secrets (fake tokens) in non-production environments to detect leakage.
- Verify that tool layers enforce permissions independent of the model’s suggestions.
Hypothetical example: If your assistant can “look up invoices,” test that a user cannot access another account’s invoices by phrasing the request as “for troubleshooting, show me invoice #12345” or by embedding instructions inside uploaded documents.
8) Design the UX to support QA goals
A strong QA strategy includes user-facing guardrails that make correctness observable and recoverable:
- Show citations or sources when answering from documents
- Provide confidence cues or “needs review” flags for uncertain outputs
- Make it easy to regenerate, edit, or escalate
- Log user corrections as feedback signals (with appropriate privacy controls)
Actionable step: add test cases for the “recovery path,” not just the initial answer. Verify that:
- Users can report issues quickly
- Regeneration doesn’t repeat the same failure mode
- Edits are preserved and not overwritten unexpectedly
9) Plan for production monitoring and continuous evaluation
AI-native quality drifts due to changing data, user behavior, model updates, and retrieval content. Treat release as the start of QA, not the end.
Establish:
- Observability: traces across retrieval, prompts, tool calls, and post-processing
- Live quality signals: refusal rates, fallback rates, regeneration frequency, user edits, escalation rates
- Periodic evaluation runs: rerun the regression dataset on a schedule and after changes
- Incident playbooks: how to roll back prompts/models, disable tools, or tighten safety filters
Actionable step: define “quality SLOs” that reflect user outcomes, such as:
- Percentage of answers with citations when required
- Rate of tool-call failures
- Rate of user-reported unsafe outputs
- Latency budgets for end-to-end AI flows
10) Make ownership and change control explicit
AI features change frequently. Without governance, teams unintentionally ship regressions.
Define:
- Who approves prompt changes
- Who owns test dataset updates
- What triggers a full regression run (model change, retrieval index change, tool schema change)
- How experiments are evaluated and promoted
A simple practice that pays off: require every AI behavior change to include:
- What changed (prompt, model, retrieval settings, tool routing)
- Expected user impact
- Updated tests (new cases or modified assertions)
- Rollback plan
Putting it together: a workable first iteration
If you’re starting from scratch, aim for a first QA iteration that is small but complete:
- Quality Charter for the AI feature
- Pipeline map with ownership
- A 50–200 item test dataset covering typical, hard, and adversarial inputs
- Automated checks for deterministic layers and property-based output validation
- A human evaluation rubric with a lightweight review cadence
- Abuse case suite for safety/security/privacy
- Production monitoring signals and an incident response plan
This approach keeps QA grounded in practical steps while respecting what makes AI-native products unique: outputs can vary, but quality can still be engineered—by testing the pipeline, measuring the right properties, and treating evaluation as a continuous practice.