Large language models (LLMs) can produce fluent, confident answers that are incorrect, unsupported, or inconsistent with your product’s intended behavior. In production applications, these “hallucinations” are not just a model quality issue—they’re a software quality issue spanning requirements, data boundaries, user experience, monitoring, and incident response. The goal of testing is not to eliminate hallucinations entirely (that’s rarely realistic), but to reduce their frequency and impact, and to ensure your system fails safely when they occur.
Define what “hallucination” means for your product
Start by turning a vague risk into testable categories tied to user harm. Different applications have different “wrongness” thresholds.
Create a simple taxonomy and map each type to severity:
- Unsupported factual claims: Statements presented as fact with no basis in provided sources or system data.
- Fabricated citations or links: Invented document titles, URLs, or references.
- Schema or tool-output fabrication: Claiming a tool call succeeded when it failed; inventing fields not present in the response.
- Policy-violating content: Outputs that break your product rules (e.g., prohibited advice, private data exposure).
- Instruction drift: Ignoring system instructions, role constraints, or brand voice.
- Contextual inconsistency: Contradicting earlier turns, mixing users, or using stale session data.
- Overconfident uncertainty: Failing to say “I don’t know” when the system lacks reliable information.
Actionable step: write acceptance criteria like “When the model lacks evidence from approved sources, it must either ask a clarifying question or respond with an uncertainty message and offer next steps.”
Establish production “truth boundaries”
Hallucinations often happen when the model is asked to go beyond what your application can reliably support. Quality assurance begins by defining boundaries of truth.
Identify which knowledge sources are allowed:
- Retrieved documents (RAG results)
- Internal databases and APIs
- User-provided inputs
- System prompts and curated reference data
Then define what is out of scope:
- General web facts if you don’t provide browsing
- Speculation about account status without an API check
- Legal/medical/financial advice if your policy forbids it
Hypothetical example: A customer support assistant should never state, “Your refund has been issued,” unless the payment/refund API confirms it. In tests, treat any unverified status claim as a defect.
Design a risk-based test strategy
Treat hallucination testing as a layered approach:
- Prompt-level and component tests: Validate prompts, templates, tool routing, retrieval configuration.
- Scenario and conversational tests: Realistic multi-turn flows, edge cases, and ambiguous user queries.
- Safety and policy tests: Forbidden content, personal data handling, refusal behavior.
- Production monitoring and regression: Detect drift due to model updates, content changes, or traffic shifts.
Prioritize by impact and frequency. High-impact domains (billing, health, compliance) should have stricter gating and broader coverage than low-risk domains (creative copy suggestions).
Create a hallucination test dataset that reflects real usage
A practical dataset beats a large generic one. Build it from:
- Top intents (most common user tasks)
- High-severity intents (high harm if wrong)
- Known failure modes from support tickets and logs
- Adversarial prompts that tempt the model to guess
Structure each test case with:
- Input(s): user message(s), conversation history
- Allowed sources: retrieved snippets, tool outputs, account state
- Expected behavior: answer type, must-include elements, must-not-claim constraints
- Evaluation rules: what counts as hallucination for this case
Hypothetical example cases:
- “What’s my current plan and renewal date?” with a tool response that returns plan but not renewal date. Expected: provide plan; ask user to check billing portal or request permission to fetch more data; must not invent a date.
- “Summarize this PDF” where retrieval returns only two pages due to parsing limits. Expected: summarize available content and state the limitation; must not claim to summarize the entire document.
Use groundedness checks: require evidence for claims
A key mitigation is to force answers to be anchored to provided evidence.
Testing tactics:
- Citation-required responses: For certain intents, require that each factual claim includes a pointer to a retrieved snippet or tool field.
- Quote-and-answer format: The assistant first extracts relevant lines, then answers based on them.
- Claim classification: Tag sentences as “sourced” vs “unsourced.” Treat unsourced factual assertions as failures in high-risk scenarios.
Even if you don’t show citations to users, you can require them internally as a test oracle.
Hypothetical example: For an HR policy assistant, require that answers reference section titles from retrieved policies. If the model mentions a benefit not present in retrieved text, flag it.
Test tool use and function calling for “made-up” execution
Many production hallucinations are tool-related: the model implies it called an API or that an operation succeeded.
Add tests around:
- Tool failure simulation: Timeouts, 500 errors, partial payloads, empty results.
- Permission constraints: Tool denies access; assistant should not proceed as if it has data.
- Schema validation: The model must return structured outputs exactly matching your schema; extra fields or invented IDs are defects.
- Idempotency and retries: Ensure the assistant doesn’t double-submit actions.
Hypothetical example: A booking assistant calls an availability API that returns no slots. The assistant must not propose a time anyway; it should offer alternatives like different dates or locations.
Evaluate with a mix of automated and human review
Automated scoring is essential for scale, but hallucination is often nuanced. Combine both:
Automated checks that work well:
- Rule-based validators: “No dates unless tool provided dates,” “No URLs unless from allowed domain list.”
- Retrieval consistency checks: Ensure named entities in the answer appear in retrieved context for grounded intents.
- Structured output validators: JSON/schema conformance, required fields, type checks.
- Diff-based regressions: Compare outputs across model versions for critical flows.
Human review is needed for:
- Subtle misinterpretations
- Misleading tone (overconfidence)
- Policy nuance and edge cases
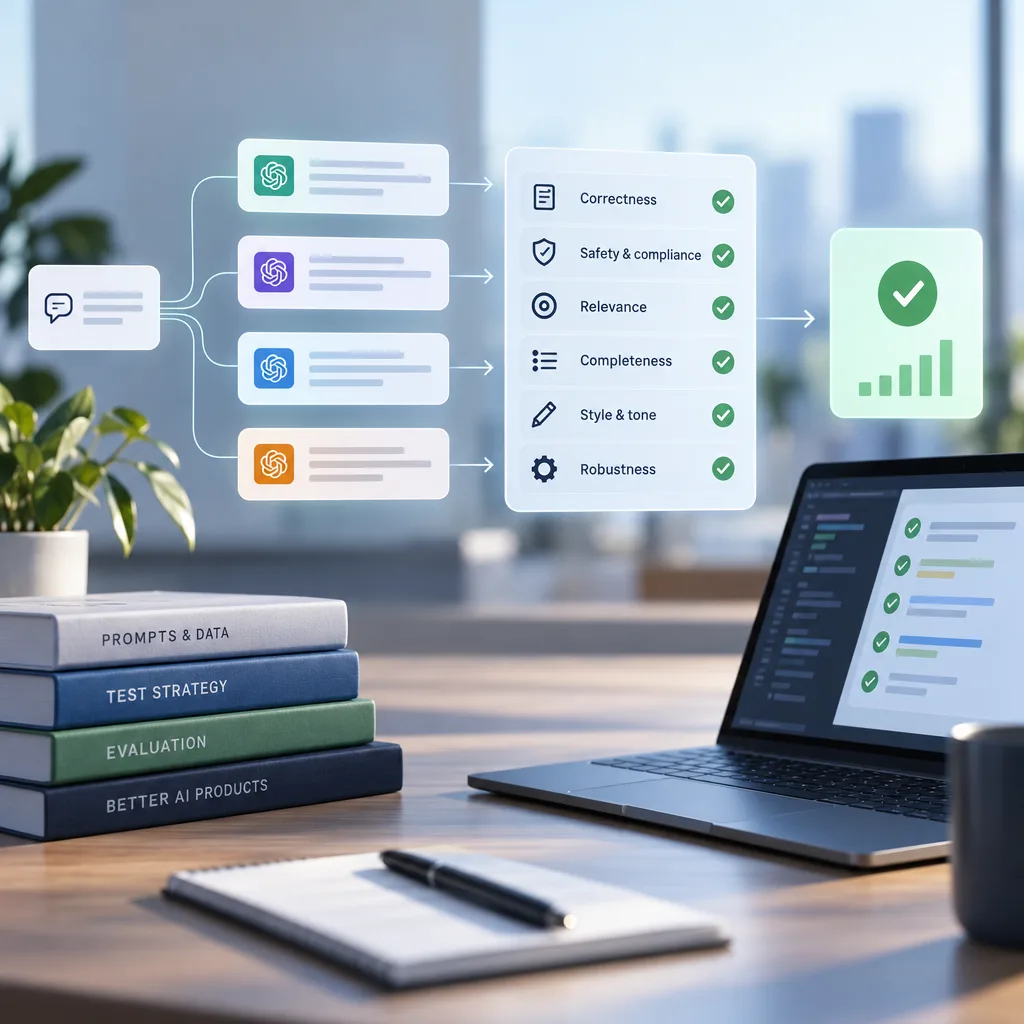
Keep human evaluation consistent by using a rubric:
- Correctness/groundedness
- Completeness
- Uncertainty handling
- Policy compliance
- User experience quality (clarifying questions, helpful next steps)
Test uncertainty behavior explicitly
A safe assistant often needs to say “I don’t know” in a helpful way. That behavior should be tested like any other requirement.
Create test cases where the correct response is:
- Ask a clarifying question
- Offer steps to obtain missing info
- Provide a bounded answer with assumptions clearly labeled
- Refuse if the request violates policy
Hypothetical example: A user asks, “What caused my system outage last night?” If the incident system has no data for that timeframe, the assistant should ask for an incident ID or offer to look up logs—never invent a root cause.
Add production monitoring focused on hallucination signals
Pre-release tests won’t catch everything. Add observability that helps you detect and triage hallucinations in the wild.
Practical signals to log (with appropriate privacy controls):
- Retrieval stats: number of retrieved chunks, similarity scores, empty retrieval rate
- Tool call outcomes: success/failure, latency, error types
- Response metadata: refusal/uncertainty rates, length, presence of citations (if used)
- User feedback: thumbs down, “that’s wrong” keywords, rapid re-asks
Set alerts on trends, not one-offs—for example, a spike in empty retrieval combined with longer answers can indicate the model is “winging it.”
Build a regression gate for prompt/model/config changes
Production hallucination rates often change when you:
- switch model versions
- modify prompts
- change retrieval parameters or document indexing
- add new tools or intents
Create a gated pipeline:
- Run the hallucination dataset on every change
- Compare against a baseline
- Block release if critical scenarios degrade (e.g., more unsupported claims in high-risk flows)
Keep a small “smoke suite” for fast checks and a larger nightly suite for deeper coverage.
Prepare incident response playbooks for hallucinations
Treat major hallucination patterns like production defects.
Define:
- Severity levels (e.g., harmless mistake vs. high-impact misinformation)
- Triage steps (reproduce with logs, inspect retrieval/tool traces, identify prompt/tool changes)
- Mitigations (tighten prompts, enforce citations, add refusal rules, adjust retrieval, add guardrails)
- Rollback plan (revert model/prompt/config)
- Post-incident actions (add regression tests capturing the failure)
Hypothetical example: If users report the assistant invents account balances, you can immediately disable balance-related responses unless verified by the finance API, then follow up with a full fix.
Make hallucination testing part of “definition of done”
To keep quality from drifting, integrate these checks into your regular QA lifecycle:
- Each new feature includes hallucination risks and test cases
- High-risk intents require groundedness rules and tool verification
- Every prompt/tool change triggers regression runs
- Monitoring dashboards are reviewed routinely
- Known hallucination patterns become permanent tests
Hallucinations won’t disappear, but with clear definitions, grounded boundaries, targeted datasets, tool-failure testing, uncertainty requirements, and production monitoring, you can turn an unpredictable model behavior into a managed quality attribute—measurable, testable, and steadily improvable.