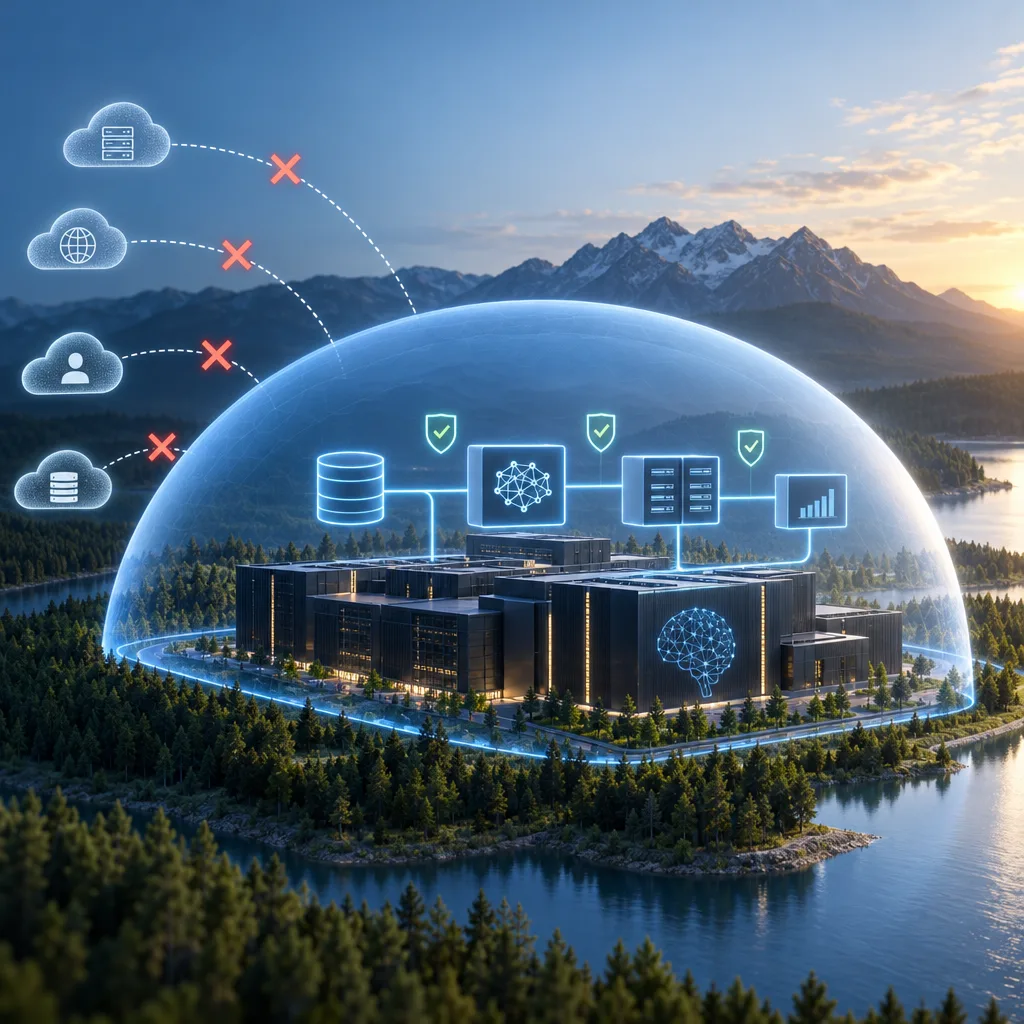
AI systems can meet every functional requirement and still violate a non-functional constraint that matters more: sovereignty. In practice, the QA problem isn’t “does the model work?” but “can we prove—repeatedly—that the full AI stack stays within approved boundaries for data, access, and operations?”
This article lays out a practical, testable approach QA teams can use to turn sovereignty objectives into verifiable checks, integrate them into release workflows, and keep them validated after go-live.
The concrete QA problem: “Sovereign on paper, non-sovereign in the edges”
Sovereignty failures often hide in places that typical application testing doesn’t cover:
- Telemetry, crash dumps, and metrics pipelines that ship data to external endpoints
- Remote administration paths (vendor accounts, management planes, break-glass access)
- Failure-mode dependencies (licensing checks, identity validation, update services)
- Data replicas (backups, caches, temporary files) created by infrastructure defaults
These issues don’t necessarily break functionality; they break commitments. The QA goal is to detect and prevent boundary violations across the entire AI delivery chain, including “invisible” services that activate under load, error, or recovery.
Step 1: Convert sovereignty statements into acceptance criteria QA can execute
Most sovereignty requirements start as policy language. QA needs them rewritten as testable acceptance criteria with unambiguous pass/fail conditions. A workable pattern is:
- Scope: what data/systems are covered (training data, inference payloads, logs, prompts, embeddings, model artifacts, admin actions).
- Boundary: what “inside” means (country, jurisdiction, specific data centers, approved networks, approved operators).
- Mechanism: how compliance is enforced (network egress controls, IAM/RBAC, key management, audit logs, deployment constraints).
- Evidence: what artifacts prove compliance (logs, flow records, configuration snapshots, attestations, audit trails).
Examples of acceptance criteria QA can request (expressed generically):
- “No workloads labeled
restrictedcan initiate outbound connections except to allowlisted internal endpoints.” - “Operational logs must be stored only in approved storage locations; no third-party log forwarding is enabled.”
- “Privileged actions must be attributable to a named identity and recorded in tamper-evident audit logs retained for N days.”
- “If external connectivity is blocked, the system must either continue in a documented degraded mode or fail safely without exporting data.”
Without explicit criteria, teams will end up “testing the app” while sovereignty breaks elsewhere.
Step 2: Map the AI data flow end-to-end (not just user-visible paths)
Sovereignty verification is largely data-flow verification. Build a data-flow map that includes:
- Ingestion sources (object stores, databases, message queues)
- Training and fine-tuning pipelines
- Model registry and artifact storage
- Inference path (API gateway → model server → GPU nodes → feature stores)
- Observability (metrics, traces, logs, APM agents)
- Support systems (ticketing integrations, notifications, email/webhooks)
- Backup, snapshot, and disaster recovery processes
A useful QA deliverable is a “flow inventory” table:
- Data category (e.g., prompts, outputs, PII-adjacent fields, system logs)
- Producer/consumer service
- Storage location(s)
- Network path and protocol
- Retention and deletion behavior
- Controls (encryption, egress allowlist, redaction)
- Test hook (what you can observe to verify)
This inventory becomes the backbone for test design and audit evidence.
Hypothetical example (for illustration only)
A team validates an inference API and confirms responses are correct. Later, they discover the tracing agent exports spans to an external endpoint by default. Functionality passed; sovereignty didn’t. A data-flow map would have flagged the tracing exporter as a data path to test and constrain.
Step 3: Design data residency tests for normal operation and “when things go wrong”
A sovereignty breach is more likely during exceptions than during the happy path. Build tests in two layers:
A) Positive-path residency checks
- Confirm all data stores used by the pipeline resolve to approved locations.
- Validate DNS resolution and routing stay within approved network boundaries.
- Verify artifact pushes/pulls (models, containers, packages) use approved registries/mirrors.
- Check that logs/metrics/traces are written only to approved sinks.
Practical QA techniques
- Use synthetic test datasets that resemble sensitive data formats without containing real sensitive data.
- Add canary fields (unique tokens) to detect leakage into logs or external systems.
- Record network egress during test runs (flow logs, firewall logs, service mesh telemetry) and compare against an allowlist.
B) Negative-path residency checks (error, retry, recovery)
Test what happens when:
- A storage write fails (does the system fall back to a different endpoint?)
- A node runs out of disk (where do crash dumps go?)
- A monitoring sink is unavailable (does it buffer locally or fail open to another service?)
- A deployment fails mid-rollout (are artifacts fetched from an external registry as fallback?)
These tests often reveal default behaviors introduced by libraries, agents, or platform tooling.
Step 4: Expand access-control testing beyond the application layer
Application RBAC can be perfect while sovereignty fails through infrastructure access. QA planning should include:
- Administrative identities: humans, vendor accounts, SRE break-glass users
- Service identities: CI/CD, provisioning tools, node agents, autoscalers
- Management interfaces: hypervisor or bare-metal controllers, cluster management planes, GPU orchestration layers, registry admins
- Revocation workflow: joiner/mover/leaver and vendor offboarding
What to test
- Role-to-permission mapping: least privilege for each role.
- Privilege escalation paths: misconfigured roles, token reuse, shared accounts.
- Location-based restrictions (where admin actions may originate), if required by policy.
- Auditability: every privileged action produces a durable, queryable record.
Artifacts QA should ask for
- IAM policy definitions and change history
- A list of privileged groups/accounts and their owners
- Audit log retention configuration and access controls
- Procedures for emergency access and post-incident review
Step 5: Run resilience tests specifically aimed at hidden external dependencies
Sovereignty can be undermined by “it works until it breaks” dependencies—especially licensing, identity, or management calls made during restart.
Create a controlled test plan that intentionally removes or blocks:
- External DNS resolution
- Non-approved outbound network routes
- Access to any non-approved authentication/licensing endpoints
- Remote management interfaces (where policy requires local-only control)
For each scenario, define expected behavior:
- Continue operating (preferred for critical services)
- Enter a documented degraded mode
- Fail safely (no data export, clear operator alerts, predictable recovery steps)
Also verify that automatic failover doesn’t violate residency—for example, by moving workloads or backups into a non-approved location due to default DR settings.
Step 6: Tie model evaluation to infrastructure configuration (to avoid “tested the wrong system”)
Model behavior and performance can change with:
- GPU type and driver versions
- CUDA/cuDNN and other dependency versions
- Model server settings (batching, quantization, memory limits)
- Container base images and kernel parameters
Sovereign testing adds a second reason to capture configuration: when infrastructure changes, sovereignty controls can change too.
Release artifacts to make mandatory
- Model version identifier and checksum
- Container image digests for serving components
- GPU/driver/runtime versions
- Configuration for logging/telemetry exporters
- Network egress policies and allowlists in effect during the test
This supports a practical re-test decision: when something changes, you can identify which sovereignty checks (and which model/performance checks) must be rerun.
Step 7: Embed sovereignty checks into CI/CD and change management
Sovereignty verification fails when treated as a one-time gate. Integrate checks at multiple points:
Automated checks (good CI candidates)
- Infrastructure-as-code policy checks (approved regions, endpoints, storage classes)
- Egress allowlist validation and “deny by default” assertions
- Container/image provenance checks (approved registries, pinned digests)
- Configuration linting for telemetry exporters and log sinks
Manual approvals (still necessary)
- Introducing a new external service dependency
- Changes to vendor/admin access terms and privileged accounts
- Jurisdiction-specific requirements that can’t be validated via automation alone
A practical workflow is a two-key gate: automated sovereignty tests must pass, and changes that expand the boundary require explicit review.
Step 8: Monitor sovereignty continuously after deployment
Passing pre-prod tests doesn’t prevent drift. Operational monitoring should look for evidence of boundary violations:
- Unexpected outbound connections or new domains/IPs
- Changes in privileged accounts, roles, or group membership
- Workloads scheduled outside approved locations (where applicable)
- Gaps in audit logging (missing events, disabled collectors, retention reduced)
- Changes to backup/replication targets
Build alerts around deviations, not just failures—because the earliest sign of a sovereignty issue may be a new integration or “helpful” configuration change.
A minimal next-step checklist for QA teams
- Draft a sovereignty requirements matrix with acceptance criteria and required evidence.
- Produce an end-to-end AI data-flow inventory including observability and failure paths.
- Implement synthetic data tests with canary fields and verify egress against an allowlist.
- Add infrastructure-level access control tests (privileged identities, auditability, revocation).
- Run resilience scenarios that block external dependencies and validate behavior.
- Record model + infrastructure configuration as part of every test run.
- Automate baseline checks in CI/CD; require manual review for boundary-expanding changes.
- Stand up post-deploy monitoring for drift: egress anomalies, privilege changes, audit gaps.
Sovereign AI is less about a single “compliant deployment” and more about maintaining demonstrable boundaries through constant change. QA’s strongest contribution is a repeatable evidence trail: each requirement mapped to tests, observed signals, and clear owners for remediation when something breaks those boundaries.