Non-deterministic AI systems don’t always give the same answer to the same input—even when nothing appears to change. That variability is often expected (and sometimes desirable), but it complicates testing: traditional “input → exact expected output” assertions break down.
This article explains how to test non-deterministic AI outputs in a way that stays practical for real teams: you’ll still ship with confidence, catch regressions early, and avoid brittle test suites.
Why AI Outputs Are Non-Deterministic (and Why It Matters)
Many AI-powered features include variability due to factors such as:
- Sampling and randomness (e.g., temperature/top-p settings)
- Model updates or configuration changes
- Long context windows where small prompt differences cascade
- Tool-using agents where external data and timing vary
- Floating-point and infrastructure differences that affect inference
For QA, the takeaway is simple: you’re not validating a single “correct” output; you’re validating a distribution of acceptable behaviors.
Start by Defining What “Quality” Means for Your AI Feature
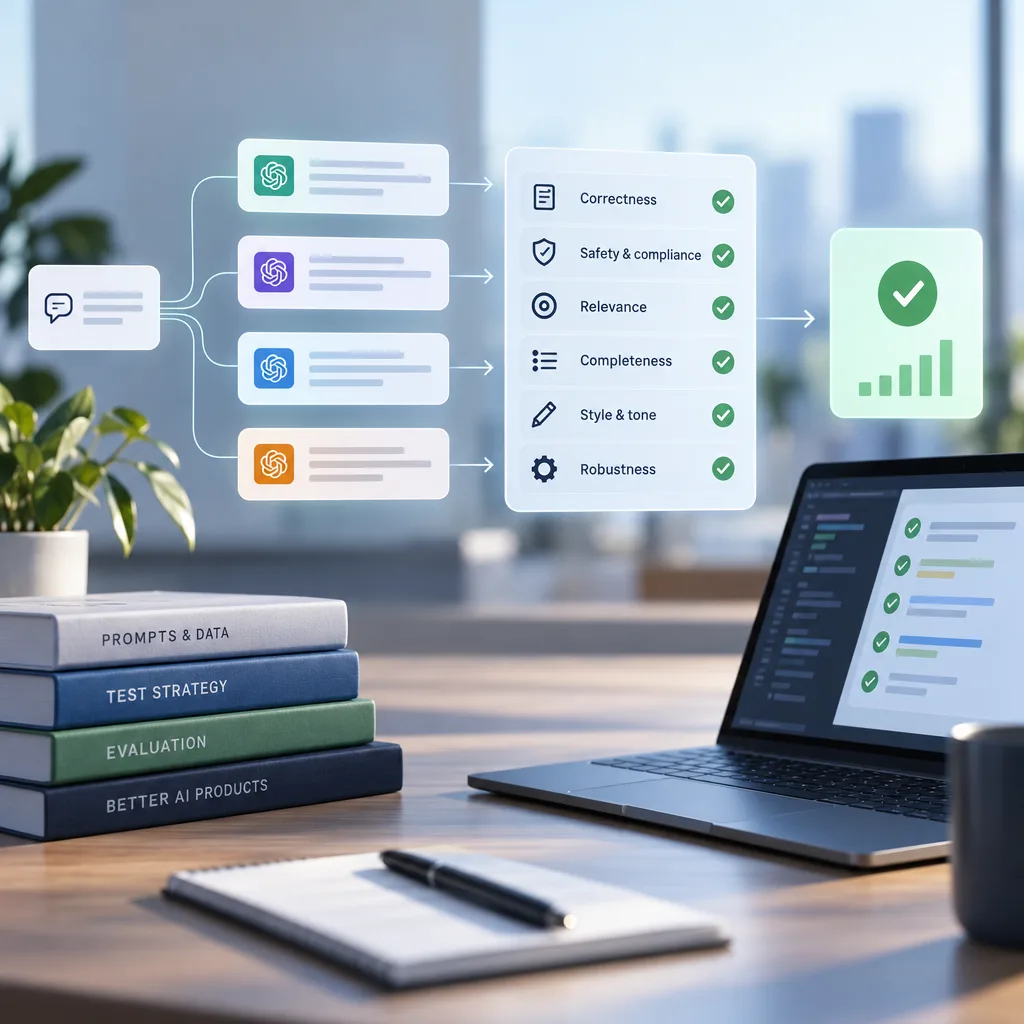
Before test design, write down the quality contract for the feature. For most AI outputs, quality is multi-dimensional.
Common quality dimensions:
- Correctness: Is the response factually/semantically correct for the task?
- Safety/compliance: Does it avoid disallowed content and respect policies?
- Relevance: Does it answer the user’s question without drifting?
- Completeness: Does it cover required fields/steps?
- Style/tone: Does it follow guidelines (format, voice, reading level)?
- Robustness: Does it handle tricky inputs and refuse when it should?
Actionable step: create a one-page “AI Output Spec” with:
- Intended user scenarios
- Must-have requirements (hard constraints)
- Nice-to-have qualities (soft constraints)
- Refusal/deflection rules
- Formatting rules (if any)
- Known limitations (what it should not attempt)
This spec becomes your “expected behavior” in the absence of deterministic expected text.
Use Constraint-Based Assertions Instead of Exact Match
Replace brittle string comparisons with assertions that check invariants—properties that must hold across valid responses.
Examples of hard constraints:
- Must include a JSON object with keys:
summary,risk_level,next_steps - Must not contain personally identifiable information beyond what the user provided
- Must cite the source documents provided in context (when required)
- Must not claim actions were taken (e.g., “I reset your password”) unless verified
Examples of soft constraints:
- Should be under 150 words for quick tips mode
- Should use bullet points for multi-step instructions
- Should ask a clarifying question if key details are missing
Hypothetical example: If you test an AI that drafts customer support replies, don’t assert exact phrasing. Assert:
- It addresses the customer’s main issue
- It uses the correct account policy snippet
- It does not promise refunds when not allowed
- It includes the required closing line and ticket ID
Separate Tests into Three Layers: Determinism, Model Behavior, and Product UX
A practical test pyramid for AI features often looks like this:
- Deterministic unit tests (non-AI)
- Prompt builders, templates, retrieval logic, business rules
- Input validation and policy gates
- Post-processing and formatting
- Model behavior tests (non-deterministic)
- Quality and safety evaluation of AI outputs
- Regression checks across versions/config changes
- End-to-end product tests
- Full user flow with the AI feature integrated
- Error handling and fallback behavior
- Latency budgets and timeouts
Actionable step: ensure the bulk of your automated coverage is in layer 1, because it’s stable and fast. Use layer 2 and 3 to validate the AI-dependent behavior without making the whole suite flaky.
Create a Stable Test Set: Golden Prompts and Challenge Prompts
Build a curated set of test inputs, each with a purpose:
- Golden prompts: representative, common user requests
- Edge prompts: ambiguous requests, missing details, contradictions
- Adversarial prompts: prompt injection attempts, policy circumvention
- Long-context prompts: inputs near context limits, multi-turn histories
- Localization prompts: language variants, mixed-language inputs
For each prompt, define:
- The scenario intent
- Required constraints (hard)
- Scoring rubric (soft)
- Any allowed variability (what can differ and still pass)
Hypothetical example: For an AI that summarizes meeting notes:
- Golden prompt: clean notes with action items
- Edge prompt: notes with conflicting decisions
- Long-context prompt: 10+ pages of notes Constraints might include:
- Must list action items as bullets
- Must preserve dates and owners if present
- Must not invent action items not in notes
Use Multiple Samples Per Test Case (But Do It Intelligently)
Because outputs vary, you can sample the model multiple times per prompt and evaluate all results.
Practical approach:
- For each test prompt, generate N outputs (e.g., 3–10) under the same settings.
- A test passes if:
- All samples meet hard constraints, and
- A high percentage meet soft constraints (define your threshold), and
- No sample triggers safety violations
This helps you catch “rare but severe” failures.
Actionable step: start small—use multiple sampling only on high-risk prompts (payments, medical advice boundaries, legal disclaimers, privacy). Expand coverage as you learn where variability hurts most.
Build a Scoring Rubric That Humans and Automation Can Both Use
A scoring rubric makes quality measurable. Keep it simple enough to be applied consistently.
Example rubric (0–2 each):
- Relevance (0: off-topic, 1: partially, 2: directly answers)
- Faithfulness (0: hallucinated, 1: minor issues, 2: grounded)
- Completeness (0: missing key parts, 1: partial, 2: complete)
- Policy compliance (0: violation, 1: borderline, 2: compliant)
- Format adherence (0/1)
You can apply the rubric via:
- Human review (for periodic audits and dataset improvements)
- Automated checks (regex/structure validation, banned phrase checks)
- Secondary AI judge models (with caution—see below)
Actionable step: run calibration sessions with reviewers using the same rubric until scoring is reasonably consistent, then lock the rubric for regression comparisons.
Combine Automated Checks: Structure, Content Rules, and Semantic Similarity
A robust automated evaluation harness usually includes:
- Structure validators
- JSON schema checks, markdown section presence, bullet count
- Content rule checks
- Forbidden claims (“guaranteed,” “100% safe”), policy keywords, PII patterns
- Grounding checks (when you have sources)
- Ensure key facts appear in provided context
- Flag named entities not present in sources
- Semantic assertions
- Check that the output includes required concepts (not exact words)
- Use embeddings or keyword sets for “must mention” items
Hypothetical example: If the AI generates release notes from commit messages:
- Must include version number
- Must mention breaking changes if any commit is labeled breaking
- Must not mention features absent from commits Semantic checks can verify the presence of key themes (“authentication,” “performance”) without requiring identical text.
Guard Against Flakiness: Control What You Can
Even though the model is non-deterministic, your test environment shouldn’t be.
Stabilization steps:
- Fix model parameters in tests (temperature, top-p, max tokens)
- Fix prompts and system instructions (version them)
- Fix retrieval inputs (snapshot the documents or use a frozen index)
- Remove time-sensitive context (“today’s date”) unless it’s the feature
- Make tool calls deterministic in test mode (stub external APIs)
- Set strict timeouts and retry rules (and log all retries)
Actionable step: whenever a test fails, capture the full “prompt package” (system + user + retrieved context + tool outputs + parameters). Without this, debugging becomes guesswork.
Regression Testing: Compare Distributions, Not Single Outputs
When updating prompts, retrieval logic, or models, you want to detect regressions without blocking harmless variation.
Practical regression tactics:
- Track pass rates per prompt (hard constraints must stay near 100%)
- Track average rubric scores and variance
- Track counts of critical failure types (policy violation, hallucination, format break)
- Run “before vs after” on the same test set and compare deltas
Hypothetical example: A change improves brevity but reduces completeness. You might accept it for a “quick answer” mode but not for “detailed guidance” mode—so separate test suites per mode.
Testing with an AI Judge: Useful, But Put Guardrails on It
Using an automated evaluator (including another AI model) can scale rubric scoring, but it introduces its own non-determinism and potential bias.
If you use AI-as-judge:
- Keep judge prompts and parameters fixed and versioned
- Validate the judge against a labeled human-reviewed dataset
- Use it for trend detection, not absolute truth
- Always hard-block on deterministic checks (schema, forbidden content)
Actionable step: treat AI judge results as “signals.” For release decisions, require either strong deterministic evidence or a targeted human review of the failures.
Make Failures Actionable: Classify and Route Them
When a test fails, the next step should be obvious. Classify failures into buckets tied to owners:
- Prompt/spec issue (update instructions, add examples)
- Retrieval issue (missing/irrelevant context, ranking problems)
- Model limitation (requires policy change or UX fallback)
- Post-processing bug (formatting, truncation, escaping)
- Product UX issue (unclear user input, missing constraints)
Actionable step: store failed cases in a “triage queue” with:
- Prompt and context snapshot
- Output and logs
- Failure category
- Suggested fix
- Link to the spec requirement violated
Putting It All Together: A Lightweight Test Plan Template
For a new AI feature, you can start with:
- 20 golden prompts, 10 edge prompts, 10 adversarial prompts
- Hard constraints defined per prompt category
- 3 samples per prompt for high-risk categories
- Automated validators + a simple rubric
- Weekly human review of a rotating subset of outputs
- Regression dashboard tracking constraint pass rate and critical failures
This approach acknowledges non-determinism without surrendering quality. You’re not trying to force identical outputs—you’re ensuring the system consistently stays within acceptable boundaries, even when the wording changes.