Location-based features fail most often when the software has to make a business decision, not when it has to draw a map. One important QA challenge to test is this:
The application produces the “right-looking” result on screen, but silently makes the wrong assignment or triggers the wrong downstream action when a location is ambiguous, stale, or near a boundary.
This article outlines a practical QA approach to prevent that class of defects—focusing on concrete decisions, test data you can trust, and next steps that make failures reproducible.
The Concrete QA Problem: Boundary Decisions That Drift Over Time
A common workflow looks like this:
- A user enters an address or shares device location.
- The app translates that into coordinates.
- The app determines which region/zone/territory/service area the point belongs to.
- The app assigns ownership (team, technician, pricing plan, tax rules, eligibility, SLA) and persists it.
The problem arises when any of the following change:
- Boundary definitions get edited (even small changes).
- Geocoding output varies (same input address resolves differently).
- Location readings are imprecise, missing, or cached.
- Permission state changes mid-journey.
- Asynchronous calls return out of order.
A map can still “look fine” while the underlying record is wrong. QA needs to test the decision, not just the display.
Step 1: Identify the Location-Controlled Decisions (Not Screens)
Start by inventorying where location influences the system. Avoid vague test targets like “map view works.” Instead, phrase test targets as decisions with observable outcomes:
- Which region is selected?
- Which record assignment is saved?
- Which users can see the result?
- Which export/report bucket changes?
- Which alerts or fees trigger?
For each decision, define:
- Inputs: device coordinate, user-chosen region, typed address, imported customer address, cached last-known coordinate, etc.
- Expected outcome: the specific region ID, assignment value, eligibility flag, or workflow state.
- Failure-mode behavior: what happens when the decision cannot be made confidently.
This last point is where many products are underspecified. If the system can’t reliably decide, does it:
- ask the user to confirm,
- allow manual override,
- mark the record as unassigned,
- or block progress?
QA should push for a clear answer before building automated tests—otherwise you’ll end up “testing the implementation,” not the product behavior.
Step 2: Build a Small Reference Dataset You Can Version
Location-based defects are hard to reproduce because the “truth” keeps moving: data updates, boundary edits, provider responses, and device signals.
Create a compact, authoritative test dataset with:
- Known-good addresses and/or coordinates
- Expected region assignments
- Boundary definitions used for that expected result
- Edge cases: near boundaries, duplicates, incomplete entries, out-of-service-area points
Keep the dataset and boundary definitions under version control. Make it routine that every test run and defect report names the dataset/boundary version.
Why small matters: large datasets blur accountability. A small set forces clarity: each case exists for a reason and proves a specific rule.
Hypothetical example (clearly labeled)
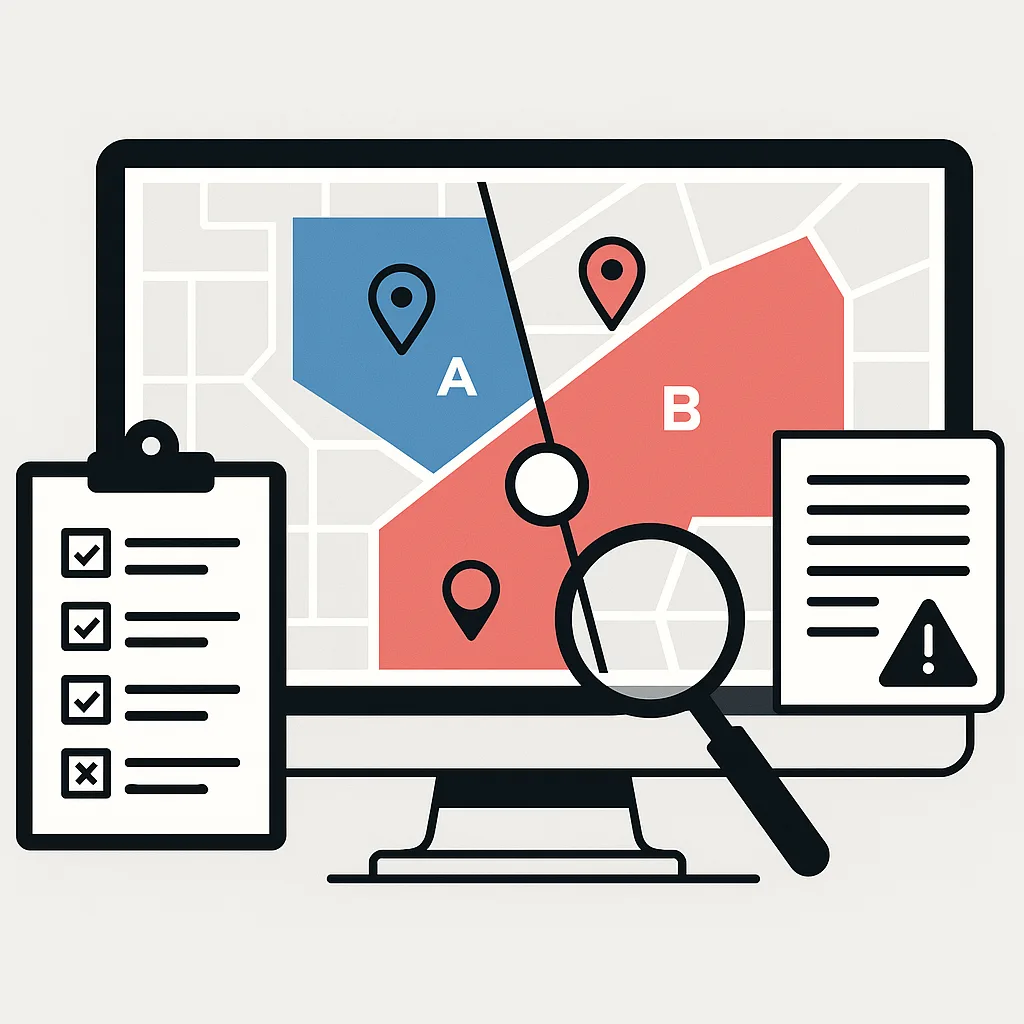
- Region A and Region B share a border along a straight line.
- Test points:
- Point 1: clearly inside A
- Point 2: clearly inside B
- Point 3: extremely close to the border on A’s side
- Point 4: exactly on the border (if your rules define this)
- Expected outcomes include both the selected region and what gets saved to the record.
Step 3: Validate Coordinate Handling as a First-Class Risk
A surprising number of “region assignment” bugs come from coordinate mishandling:
- swapped latitude/longitude,
- wrong coordinate reference assumptions,
- malformed numeric formats,
- missing values treated as zero,
- “valid-looking” coordinates that point to the wrong place.
Treat coordinate ingestion like any other critical input validation area:
- Assert format rules (including order expectations).
- Test missing values and nulls.
- Test swapped values that still land on Earth (so the app can’t pass by merely checking “is numeric”).
The key QA design principle: tests must detect plausible wrong inputs, not just obviously broken ones.
Step 4: Address Matching Isn’t Binary—Test Uncertainty Explicitly
If users can type an address, QA must test how the system behaves when the geocoder returns an uncertain match. A returned coordinate is not proof the original address was matched precisely.
Design cases such as:
- missing building number,
- similar street names,
- incomplete postal codes,
- abbreviated or localized address formats,
- ambiguous city/state combinations.
Then assert what the product should do:
- auto-accept only high-confidence matches?
- require confirmation on partial/ambiguous matches?
- allow manual pin drop or region selection?
Make sure your acceptance criteria reflect the business risk. Eligibility, pricing, taxes, and dispatch assignment often cannot tolerate silent ambiguity.
Step 5: Boundary Testing Must Verify Rules, Not Just Polygons
Boundary edits are inevitable. QA’s job is to ensure the system still makes consistent assignments across:
- the UI,
- persisted records,
- dashboards,
- exports,
- and APIs.
Testing the colors on a map is not enough; you need direct assertions that:
- region membership is correct for each test point,
- saved assignments match the calculation,
- downstream views match the saved state (not a recalculated state with different inputs).
Also force explicit agreement on tricky rules:
- What if regions overlap?
- What if there’s a gap between regions?
- What if a point is exactly on the boundary?
- Are “holes” inside a region possible (excluded sub-areas)?
- For global use, what happens near longitude wrap-around?
If product and engineering haven’t agreed, QA should escalate: boundary ambiguity becomes customer-impacting randomness.
Step 6: Permissions and Location Quality Are Separate Test Axes
Treat permission state as its own test matrix dimension, not a one-time setup step:
- first-time prompt accepted/denied,
- previously granted then revoked,
- approximate vs precise (where applicable),
- background/foreground restrictions.
Separately, test location quality fields (e.g., timestamp and accuracy radius where available):
- stale readings (just inside vs just outside your acceptance threshold),
- low-accuracy readings whose radius crosses a boundary,
- “location unavailable” paths.
A robust product should not treat the center-point coordinate as truth when the accuracy radius indicates uncertainty.
Hypothetical example (clearly labeled)
A workflow requires “current location.” QA injects:
- a fresh accurate reading inside Zone A → should assign A
- an old reading inside Zone A → should prompt refresh or warn
- a reading near boundary with wide accuracy radius spanning Zones A and B → should require confirmation or avoid auto-assigning
Step 7: Movement Scenarios Test “What Happens Next,” Not Just “Where Am I”
Many location features depend on sequences:
- entering/leaving a zone,
- dwell time requirements,
- repeated updates,
- background behavior.
Build tests that replay movement:
- start outside → enter → pause → exit
- include small jitter around the boundary to detect flapping
- verify the business action sequence (notifications, assignments, state changes), not just marker movement
Also validate interruption conditions in a targeted real-device suite:
- app backgrounded,
- screen locked,
- battery-saving modes,
- connectivity loss and recovery.
Browser or emulator simulation helps with repeatability, but it should not be treated as proof of physical-device behavior.
Step 8: External Service Failures Need Distinct Recovery Paths
When geocoding, routing, or map services fail, don’t lump all failures into “lookup failed.”
Test distinct scenarios:
- no results vs request denied vs rate/usage limits,
- timeout vs slow response,
- malformed response,
- out-of-order responses (older request finishes after a newer one).
QA should assert that:
- loading indicators stop correctly,
- the message tells the user what to do next,
- retries are bounded,
- stale responses don’t overwrite newer user intent.
If your product supports offline flows, confirm that sync does not duplicate actions or treat stored location as live.
Step 9: Make Location Defects Reproducible by Design
Location bugs become expensive when they can’t be replayed. Standardize what must be captured in every issue:
- input address or coordinates,
- timestamp and accuracy (if available),
- permission state,
- device/OS and app build,
- boundary dataset version,
- the expected business outcome (not “map wrong”),
- for movement: the full sequence of readings.
This turns “can’t reproduce” into an actionable checklist item, not a dead end.
Next Steps: A Practical Implementation Plan
- Run a decision workshop: list every business outcome controlled by location and define failure-mode behavior.
- Create a versioned location fixture: small dataset + boundary definitions + expected assignments.
- Add rule-level automated checks: coordinate validation, region membership, overlap rules, persisted assignment integrity (API/unit tests where possible).
- Add a focused end-to-end suite: the critical user journeys that connect input → decision → save → downstream views.
- Maintain a small real-device matrix: permissions, backgrounding, movement, and recovery paths.
- Adopt a defect reporting template: enforce reproducibility fields for every location-related bug.
Location QA becomes reliable when the team stops treating the map as the product—and starts treating location as an input to consequential, testable decisions.
Background reading: Software Testing Magazine. This article presents Anbosoft’s own analysis and recommendations.